Envision3D: Efficient Dense Views Generation
with Anchor Views Interpolation for Image to 3D
with Anchor Views Interpolation for Image to 3D
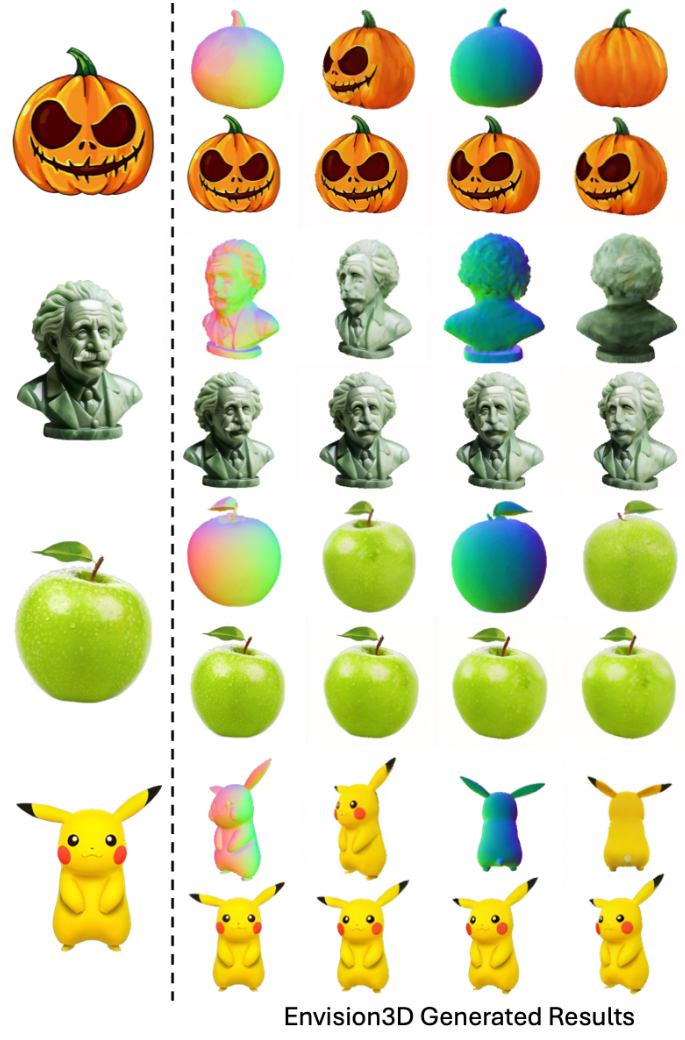
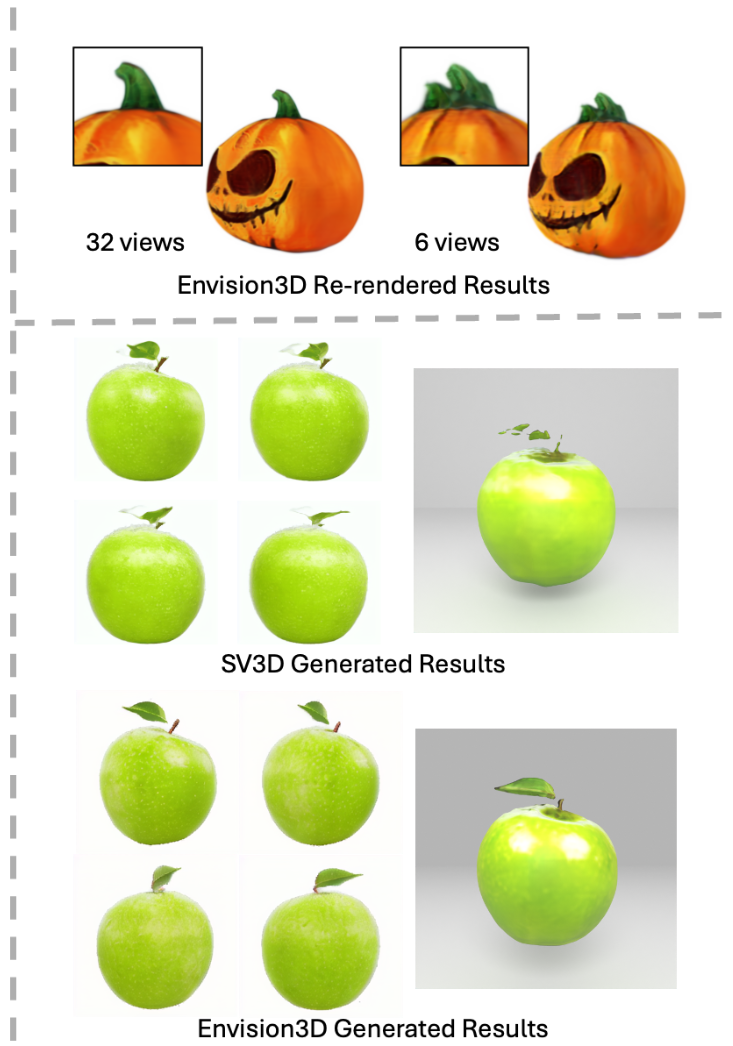
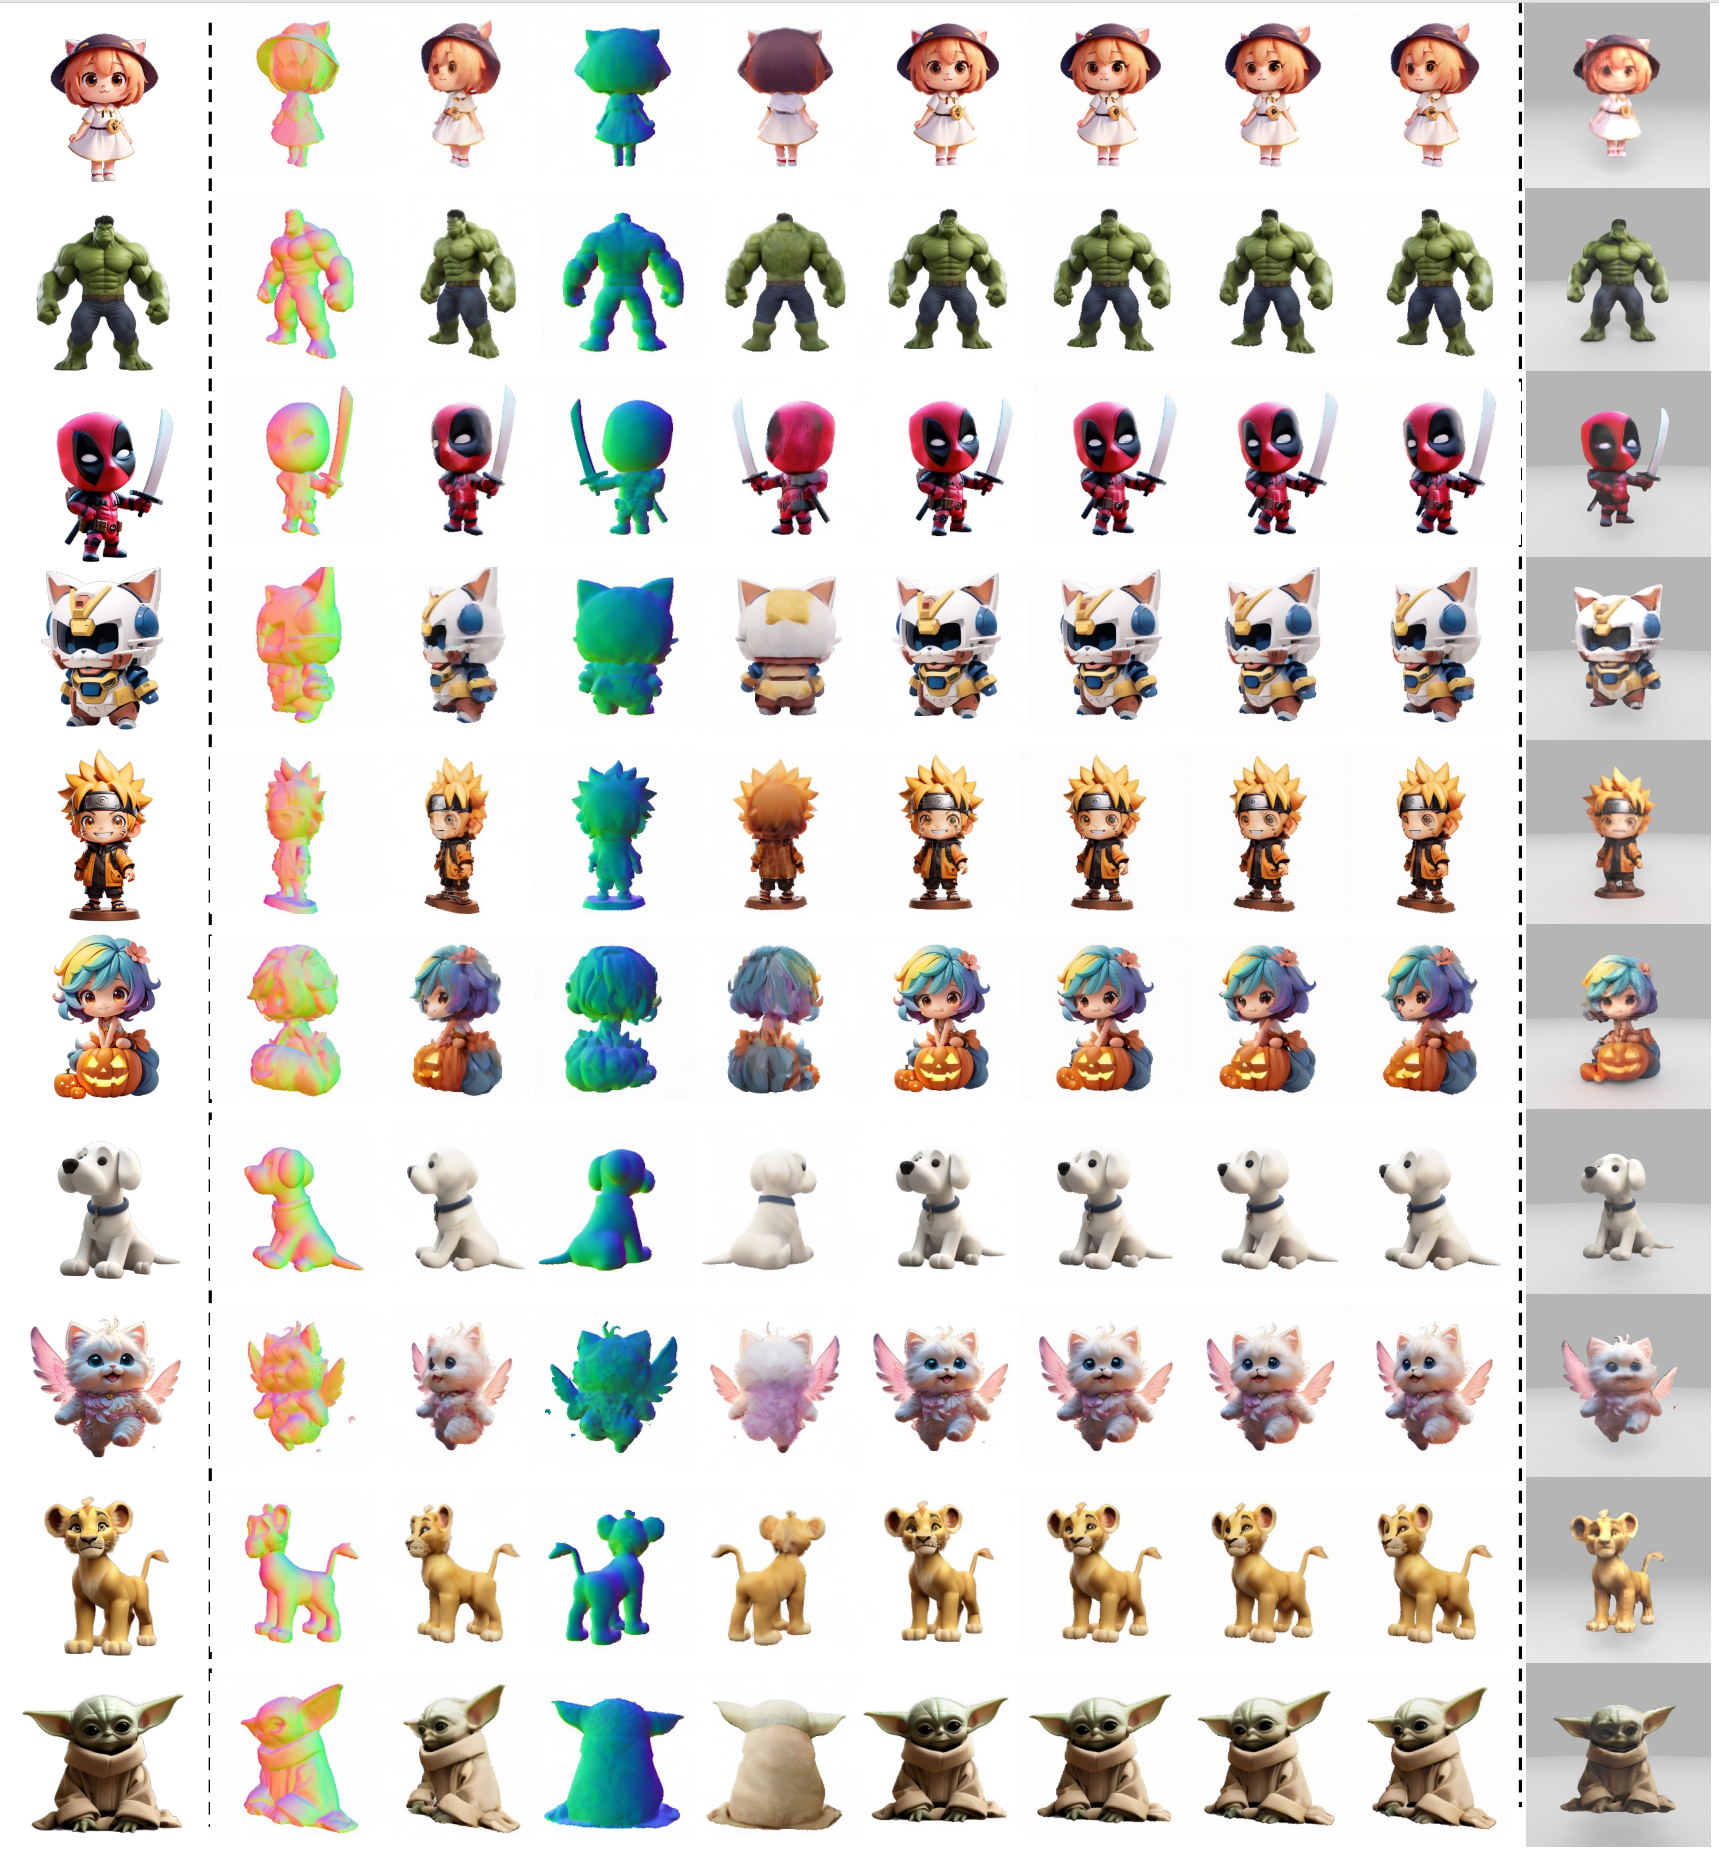
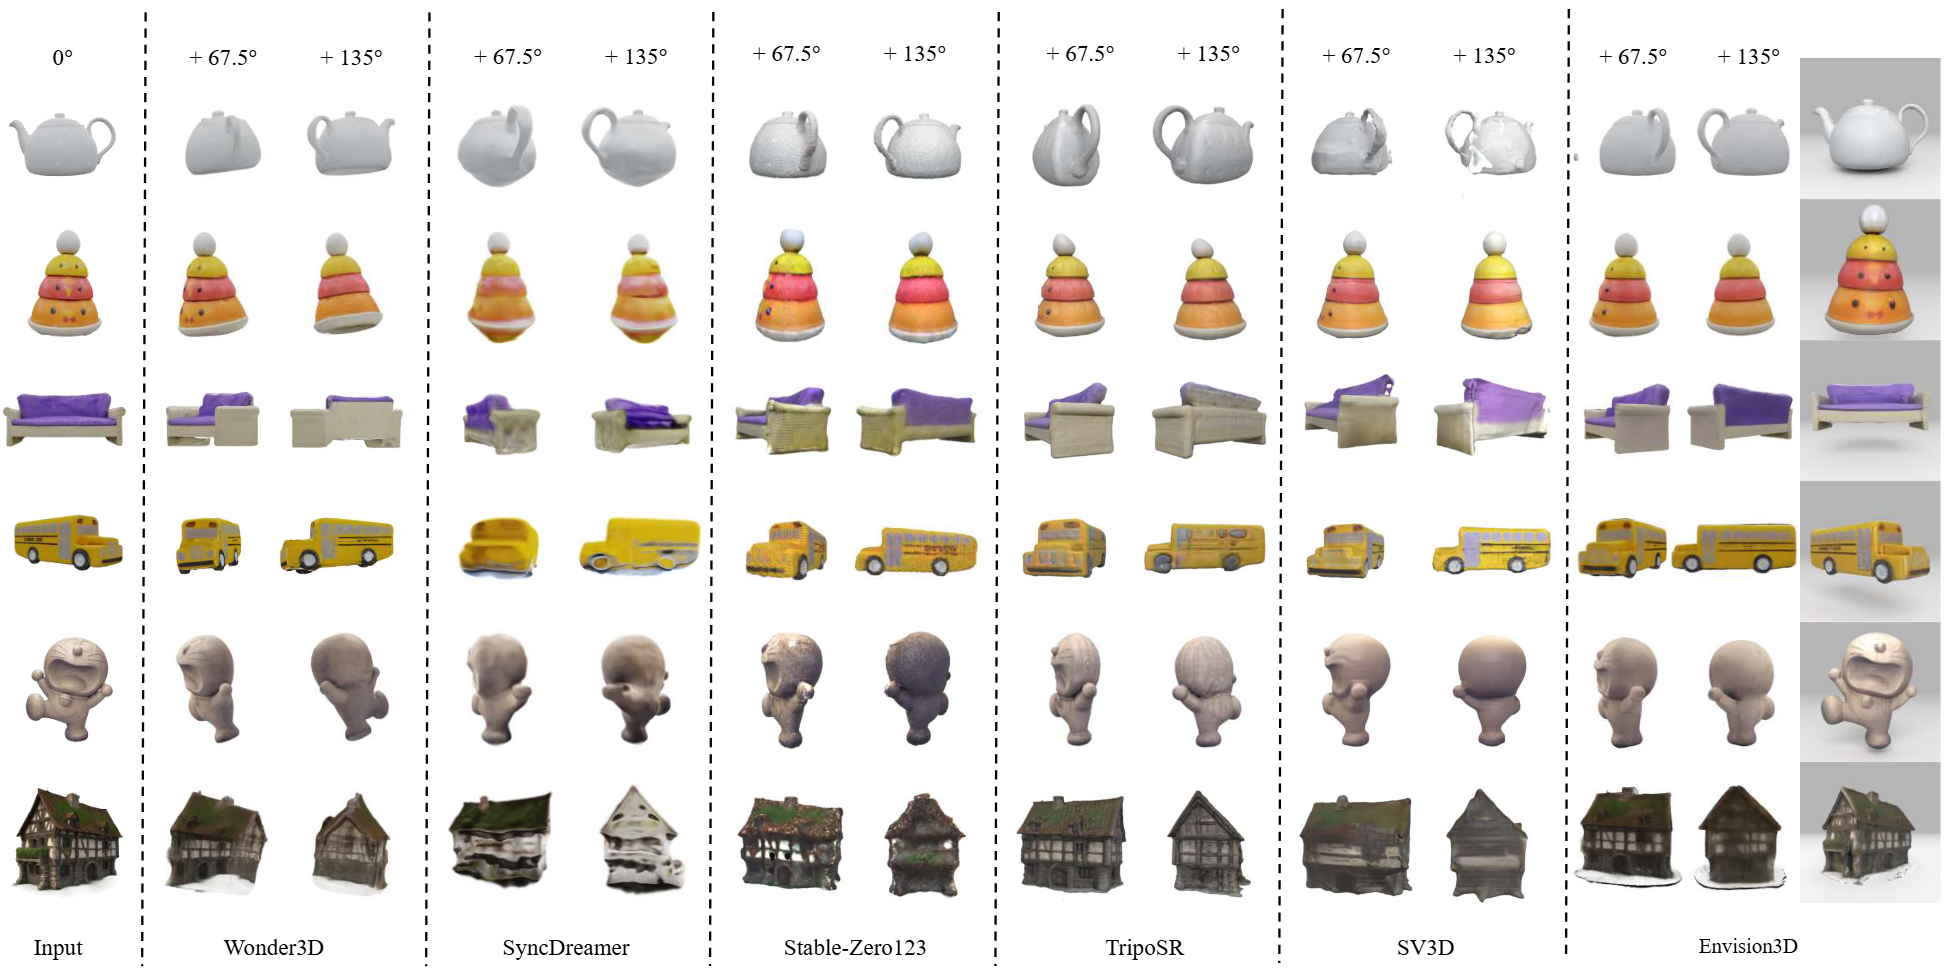
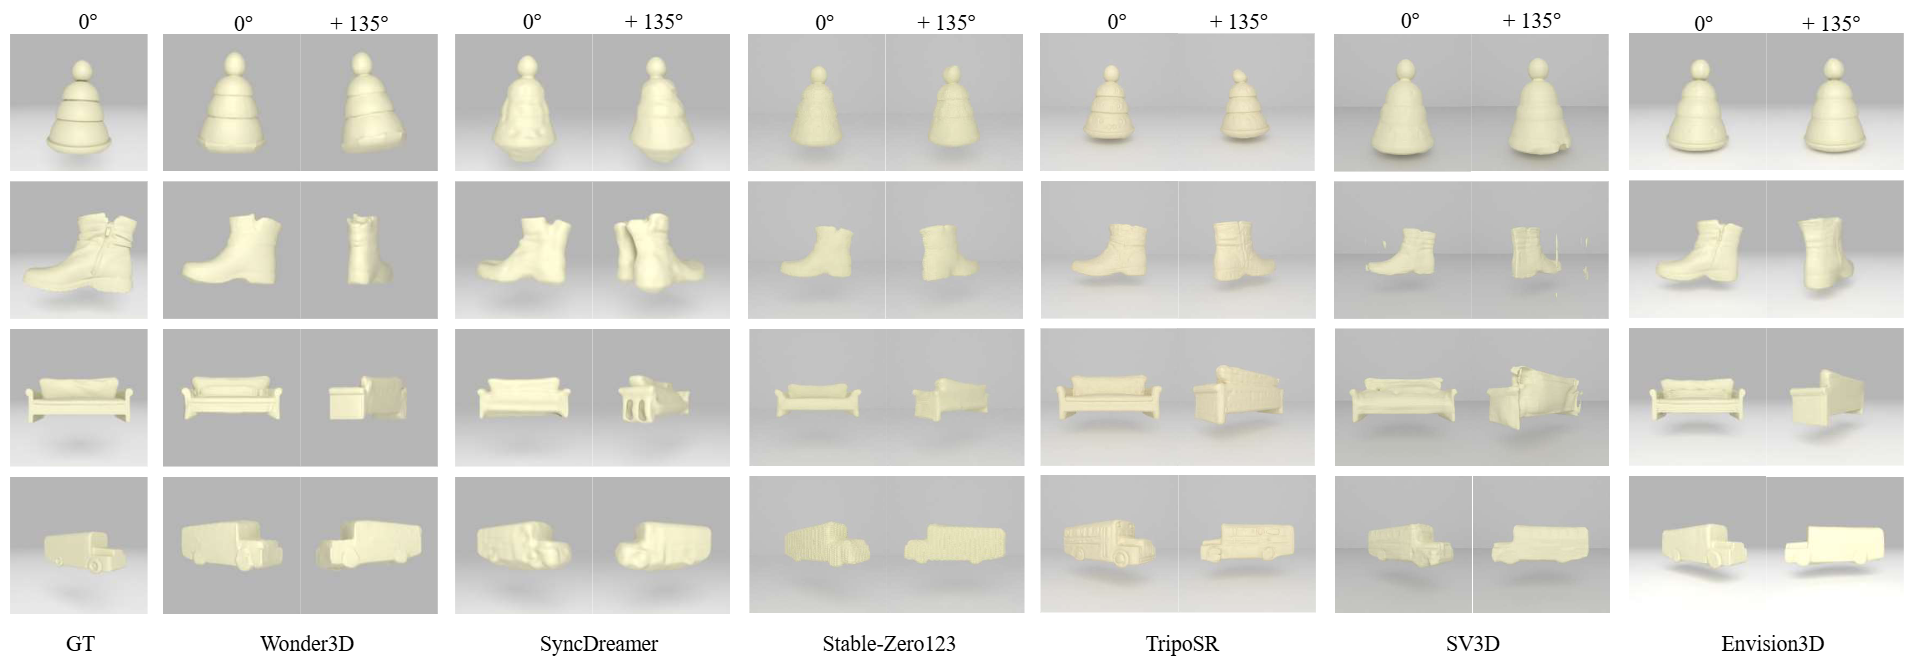
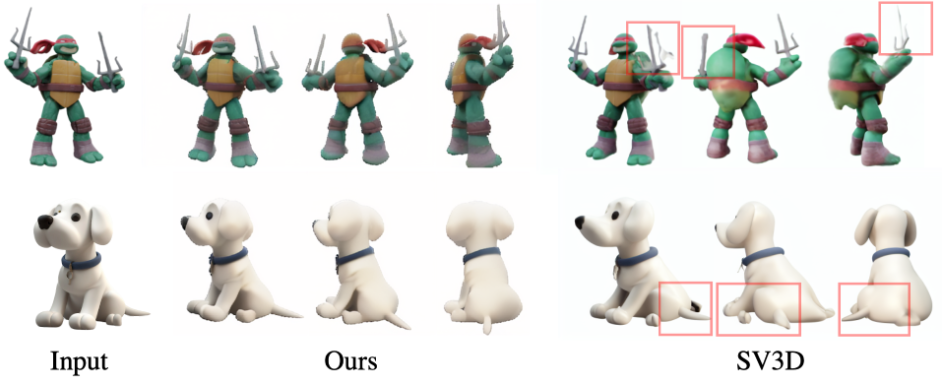
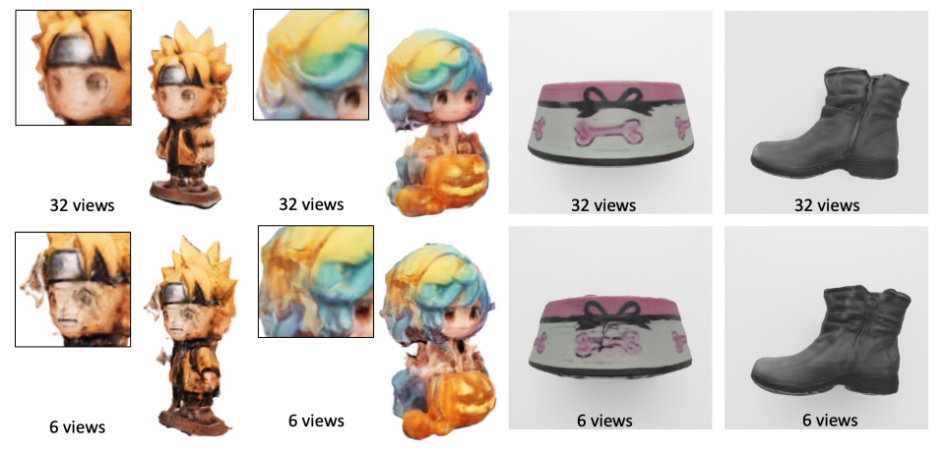
We show on the left side that Envision3D generates 32 dense, multi-view consistent images and extracts high-quality 3D content from one input image. On the top right side, we present that incorporating fewer views leads to low-quality 3D content. On the bottom right side, we highlight the superior consistency of our method across different views compared to the video diffusion model-based method.
Results
Comparison
Envision3D (Ours)
Ablation Studies
Additional Results